RK®
Senior Backend & Data Engineer

Java · Spring Boot · Distributed Systems · Data Platforms · Azure

I build the quiet systems that keep business moving.

Senior backend engineer with 10+ years building Java, Spring Boot, and Kubernetes microservices for telecom and finance.

60% ↓
upload latency
40% ↓
feed onboarding
25% ↓
operational overhead
Layered arches in charcoal, terracotta and orange with a circuit motif
JAVA / SPRING BOOT
MICROSERVICES / REST
AZURE / KUBERNETES
NEXT.JS / TYPESCRIPT

Case Studies

01

TD Securities (Endava)

Data Engineer · Toronto

Cut file-upload latency and feed onboarding on a Java data platform

Hired to modernize data-intensive paths on AKS. Owned the upload pipeline and source-onboarding experience end to end — from batch windows that stalled operators to config-driven loaders and latency outcomes a hiring manager can probe in an interview.

OWNED

End-to-end ownership of the file-upload path and API source onboarding for platform consumers.

BEFORE → AFTER

Multi-minute batch upload windows and week-scale API source onboarding → 60% ↓ upload latency and 40% ↓ feed onboarding via a config-driven API Source Loader, with OTel → Datadog so regressions surface in ops.

INTERVIEW

"How did you keep the loader config-driven without turning every new feed into a deploy?"

  • •Drove upload processing from multi-minute batch pain to a measurable latency win (60% ↓).
  • •Shipped config-driven API Source Loader so new feeds land in days-class cycles (40% ↓), not weeks.
  • •Instrumented Spring services (OpenTelemetry → Datadog) so performance regressions show up in ops, not war rooms.
  • •Split deployable modules, containerized Spring Boot, and Helm-charted repeatable AKS deploys.
  • •Java/Spring POCs for Iceberg → Unity Catalog Delta via Spark/Databricks — mention as supporting modernization, not the lead hire signal.

Java · Spring Boot · AKS · Helm · OpenTelemetry · Datadog · Spark/Databricks · Iceberg/Delta

Source APIsConfig-driven LoaderSpring Boot ServicesKafka · Data ProcessingSpark · DatabricksDelta Lake · Unity Catalog
BEFORE20 minAFTER<2 min10× fasterfile-upload processing time
02

Amdocs Canada

Software Developer · Toronto

ART — Automatic Recovery Tool for billing data integrity

Built a Spring Boot recovery console operators actually use: detect inconsistencies, emit actionable reports, and remediate without opening an engineering ticket for every incident — cutting operational overhead instead of adding queue noise.

OWNED

Designed and delivered ART for ops inconsistency detection and remediation workflows.

BEFORE → AFTER

Manual chase of inconsistent billing/ops data → 25% ↓ operational overhead with a detect → report → remediate loop.

INTERVIEW

"What's the difference between a recovery tool operators trust and one they ignore?"

  • •Detect data inconsistencies early with reports ops can act on (not raw dumps).
  • •Remediation path that does not require an engineer on every incident.
  • •Outcome: 25% ↓ operational overhead on the recovery workflow.
  • •Concurrent Pub/Sub debit/surcharge pipelines and AWS Spring services — context for volume, not a second headline.

Java · Spring Boot · Thymeleaf · AWS · Pub/Sub

03

Personal · Toronto

Systems practice (self-hosted)

Homelab as a production-style reliability gym

Long-running self-hosted platform used to rehearse the same habits as production backends: named blast-radius boundaries, ingress + identity at the edge, and observability you actually look at. The Selected Builds card shows the fleet topology; this study is about the operating posture.

OWNED

Sole operator — design, secure, and run the fleet end to end.

BEFORE → AFTER

Single-box ad-hoc containers → named hosts, plane separation (edge / apps / data), and fleet monitoring you can query when something breaks.

INTERVIEW

"What did running your own edge teach you that a cloud tutorial did not?"

  • •Treat media (Plex/Jellyfin/Immich) as a workload line, not the résumé lead — the hire signal is edge, identity, and fleet ops.
  • •Practice incident isolation: edge failure should not take apps or data planes with it.
  • •Prefer boring ops UX (Beszel / Dozzle / Homarr) so health and logs are habitual, not heroic.

Traefik · CrowdSec · Authelia · Pangolin · Docker · Beszel · Dozzle · Homarr

Selected Builds

Self-hosted platform

Homelab — production-style edge, identity & fleet ops

Six-host fleet with Traefik/CrowdSec/Authelia at the edge, app nodes, media as a workload line, and Beszel/Dozzle/Homarr across the board — not "I run Plex."

Sole operator of a six-host edge / apps / data fleet with shared monitoring.

BEFORE → AFTER

Ad-hoc containers on one box → named hosts, ingress + authz, observability, and clear blast-radius boundaries.

TALKING POINT

"Walk me through how you'd isolate a compromised edge node without taking the media or app planes down."

  • •Edge/ingress plane: Traefik + CrowdSec + Authelia (+ Pangolin) on hlx-prod-rpi-01 / hlx-edge-01
  • •App plane: Docker hosts + balerion — services with Unmanic where needed
  • •Fleet ops: Beszel / Dozzle / Homarr for health, logs, and ops UX across all six hosts
Traefik
CrowdSec
Authelia
Pangolin
Docker
Beszel
Dozzle
Homarr

TD Securities · via Endava

Cut file-upload latency and feed onboarding on a Java data platform

Owned the path from slow batch uploads and week-long source onboarding to config-driven loaders and measurable latency wins — Spring on AKS, with observability wired for real ops.

End-to-end ownership of upload path + source onboarding UX for platform consumers.

BEFORE → AFTER

Uploads stuck in long batch windows; new API sources took weeks to land → 60% ↓ upload latency, 40% ↓ feed onboarding time via config-driven API Source Loader.

TALKING POINT

"How did you keep the loader config-driven without turning every new feed into a deploy?"

  • •Drove upload processing from multi-minute batch pain to a latency outcome hiring managers can probe (60% ↓)
  • •Shipped config-driven API Source Loader — onboarding measured in days-class cycles (40% ↓)
  • •Instrumented Spring services (OTel → Datadog) so regressions show up in ops, not in war rooms
Java
Spring Boot
AKS
Helm
OpenTelemetry
Datadog
Spark/Databricks

Amdocs Canada

ART — Automatic Recovery Tool for billing data integrity

Built a Spring Boot recovery console that detects inconsistencies, produces actionable reports, and supports remediation — cutting operational overhead instead of adding another ticket queue.

Designed and delivered ART used by ops for inconsistency detection and remediation workflows.

BEFORE → AFTER

Manual chase of inconsistent billing/ops data → 25% ↓ operational overhead with detect → report → remediate loop.

TALKING POINT

"What's the difference between a recovery tool operators trust and one they ignore?"

  • •Detect data inconsistencies early with actionable reports (not raw dumps)
  • •Remediation path operators can run without engineering on every incident
  • •Outcome: 25% ↓ operational overhead on the recovery workflow
Java
Spring Boot
Thymeleaf
AWS

Also ships UI

Full-stack product surfaces — secondary to platform work above.

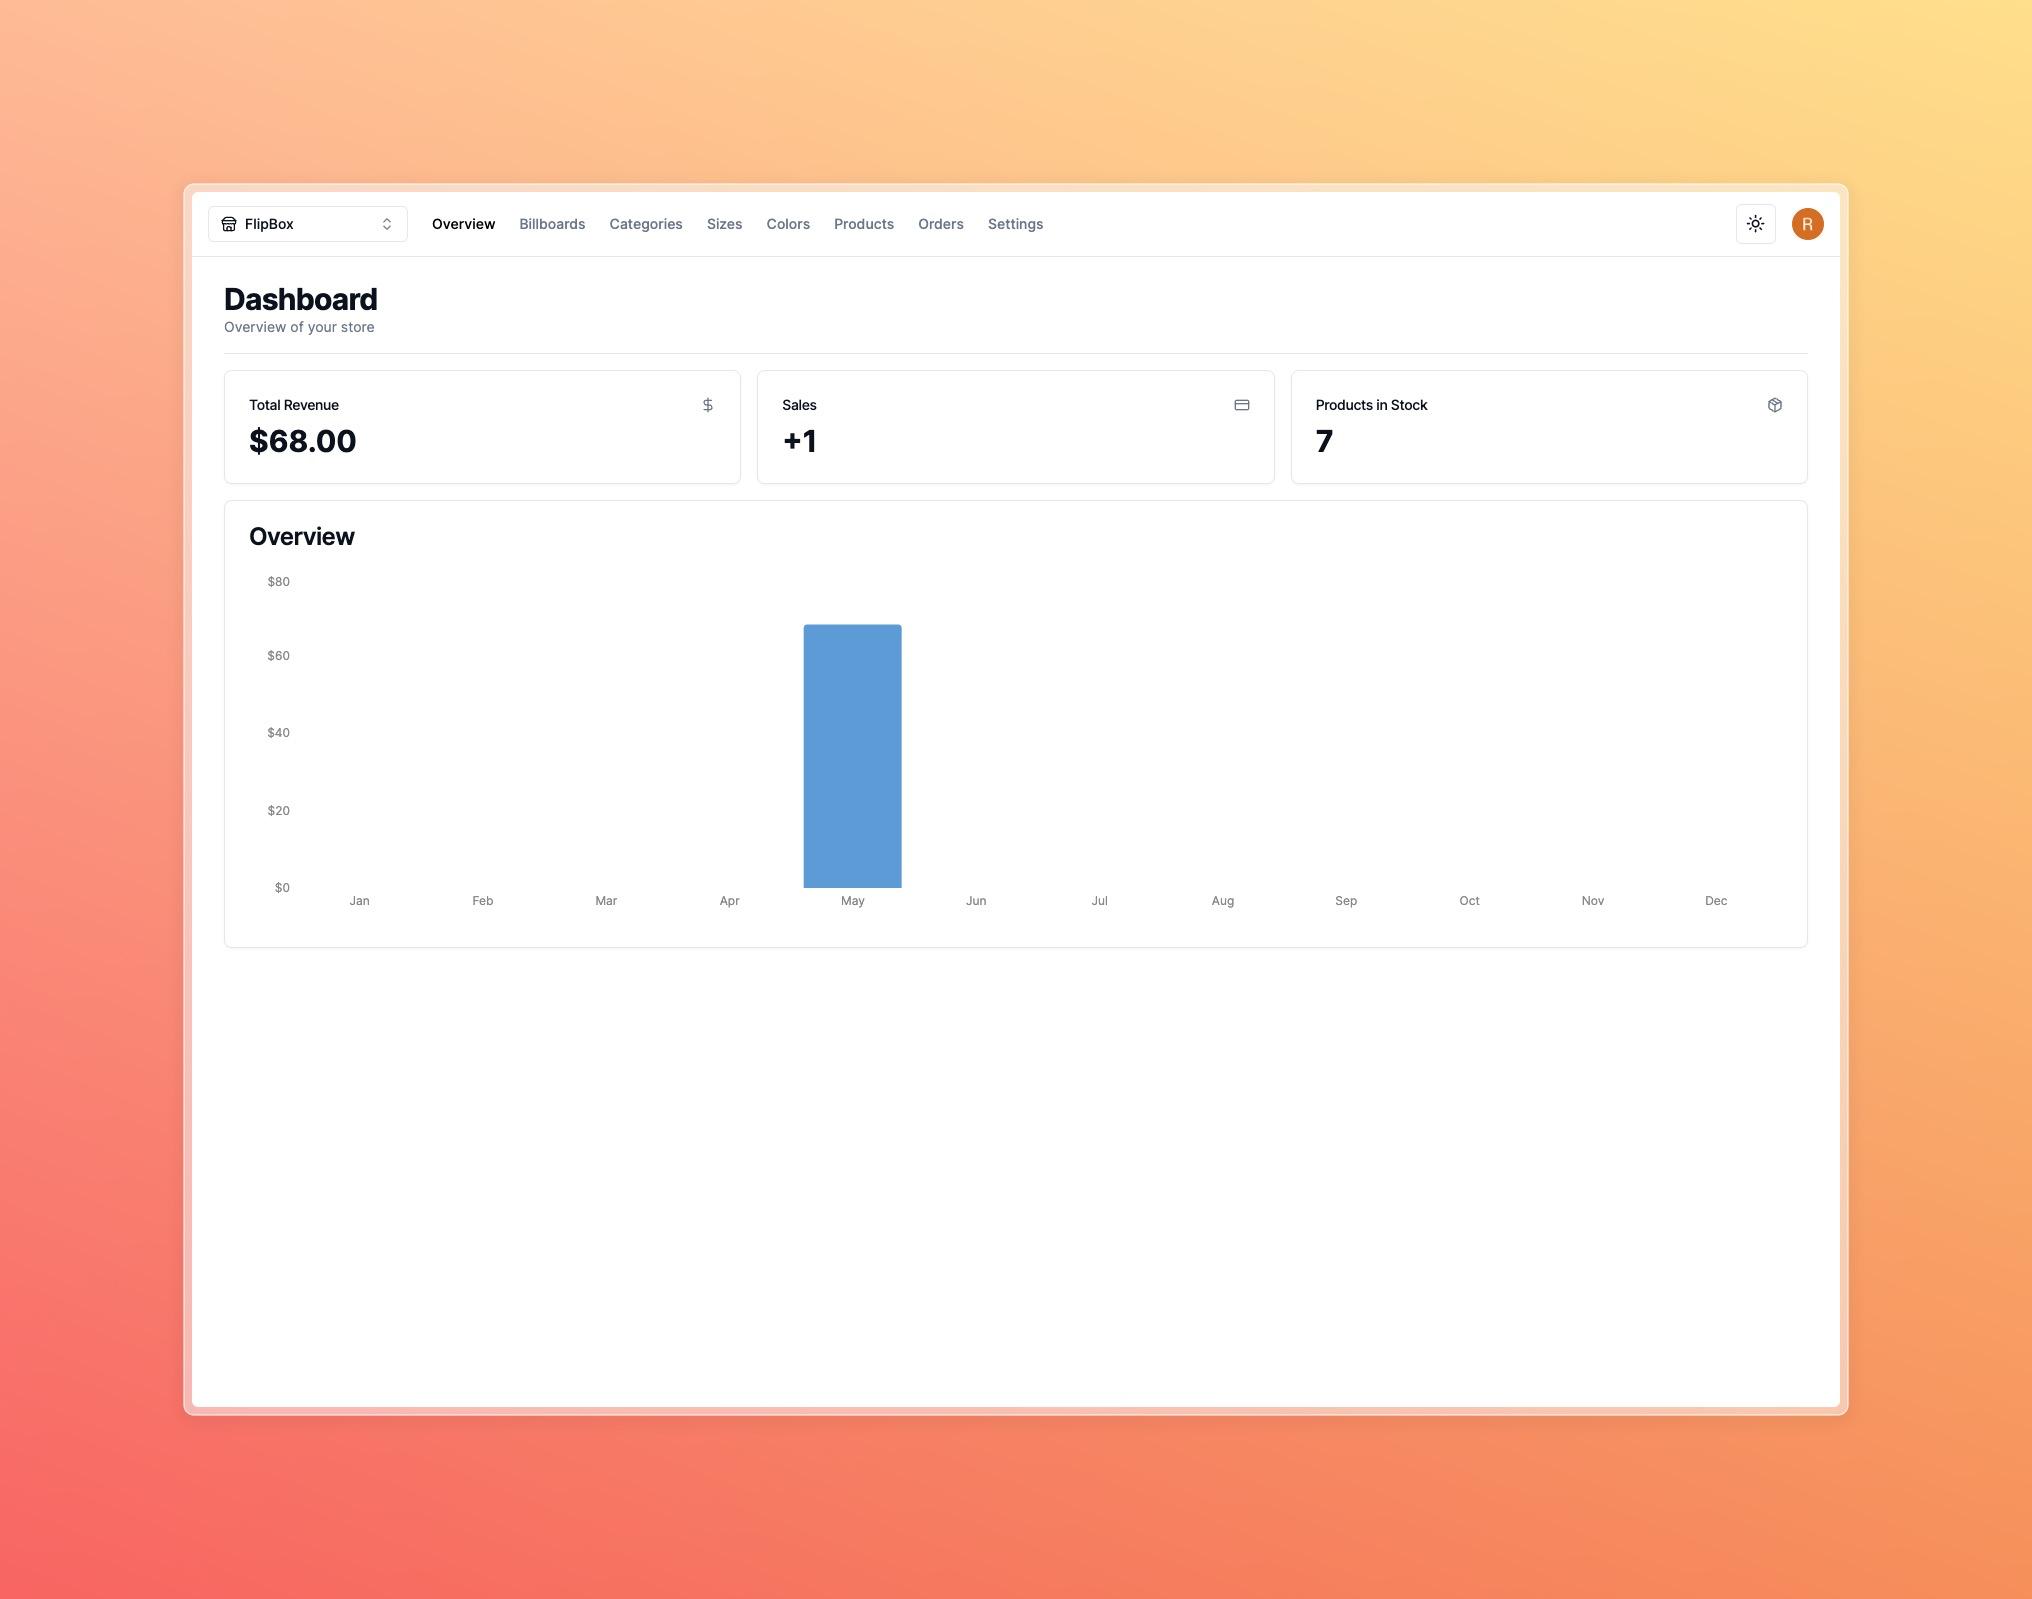
E-commerce admin

E-commerce admin

Multi-tenant admin dashboard for managing products, orders, and analytics. Built with Next.js, integrated with Stripe for payments and Clerk for authentication.

Next.js
React
Stripe
Clerk
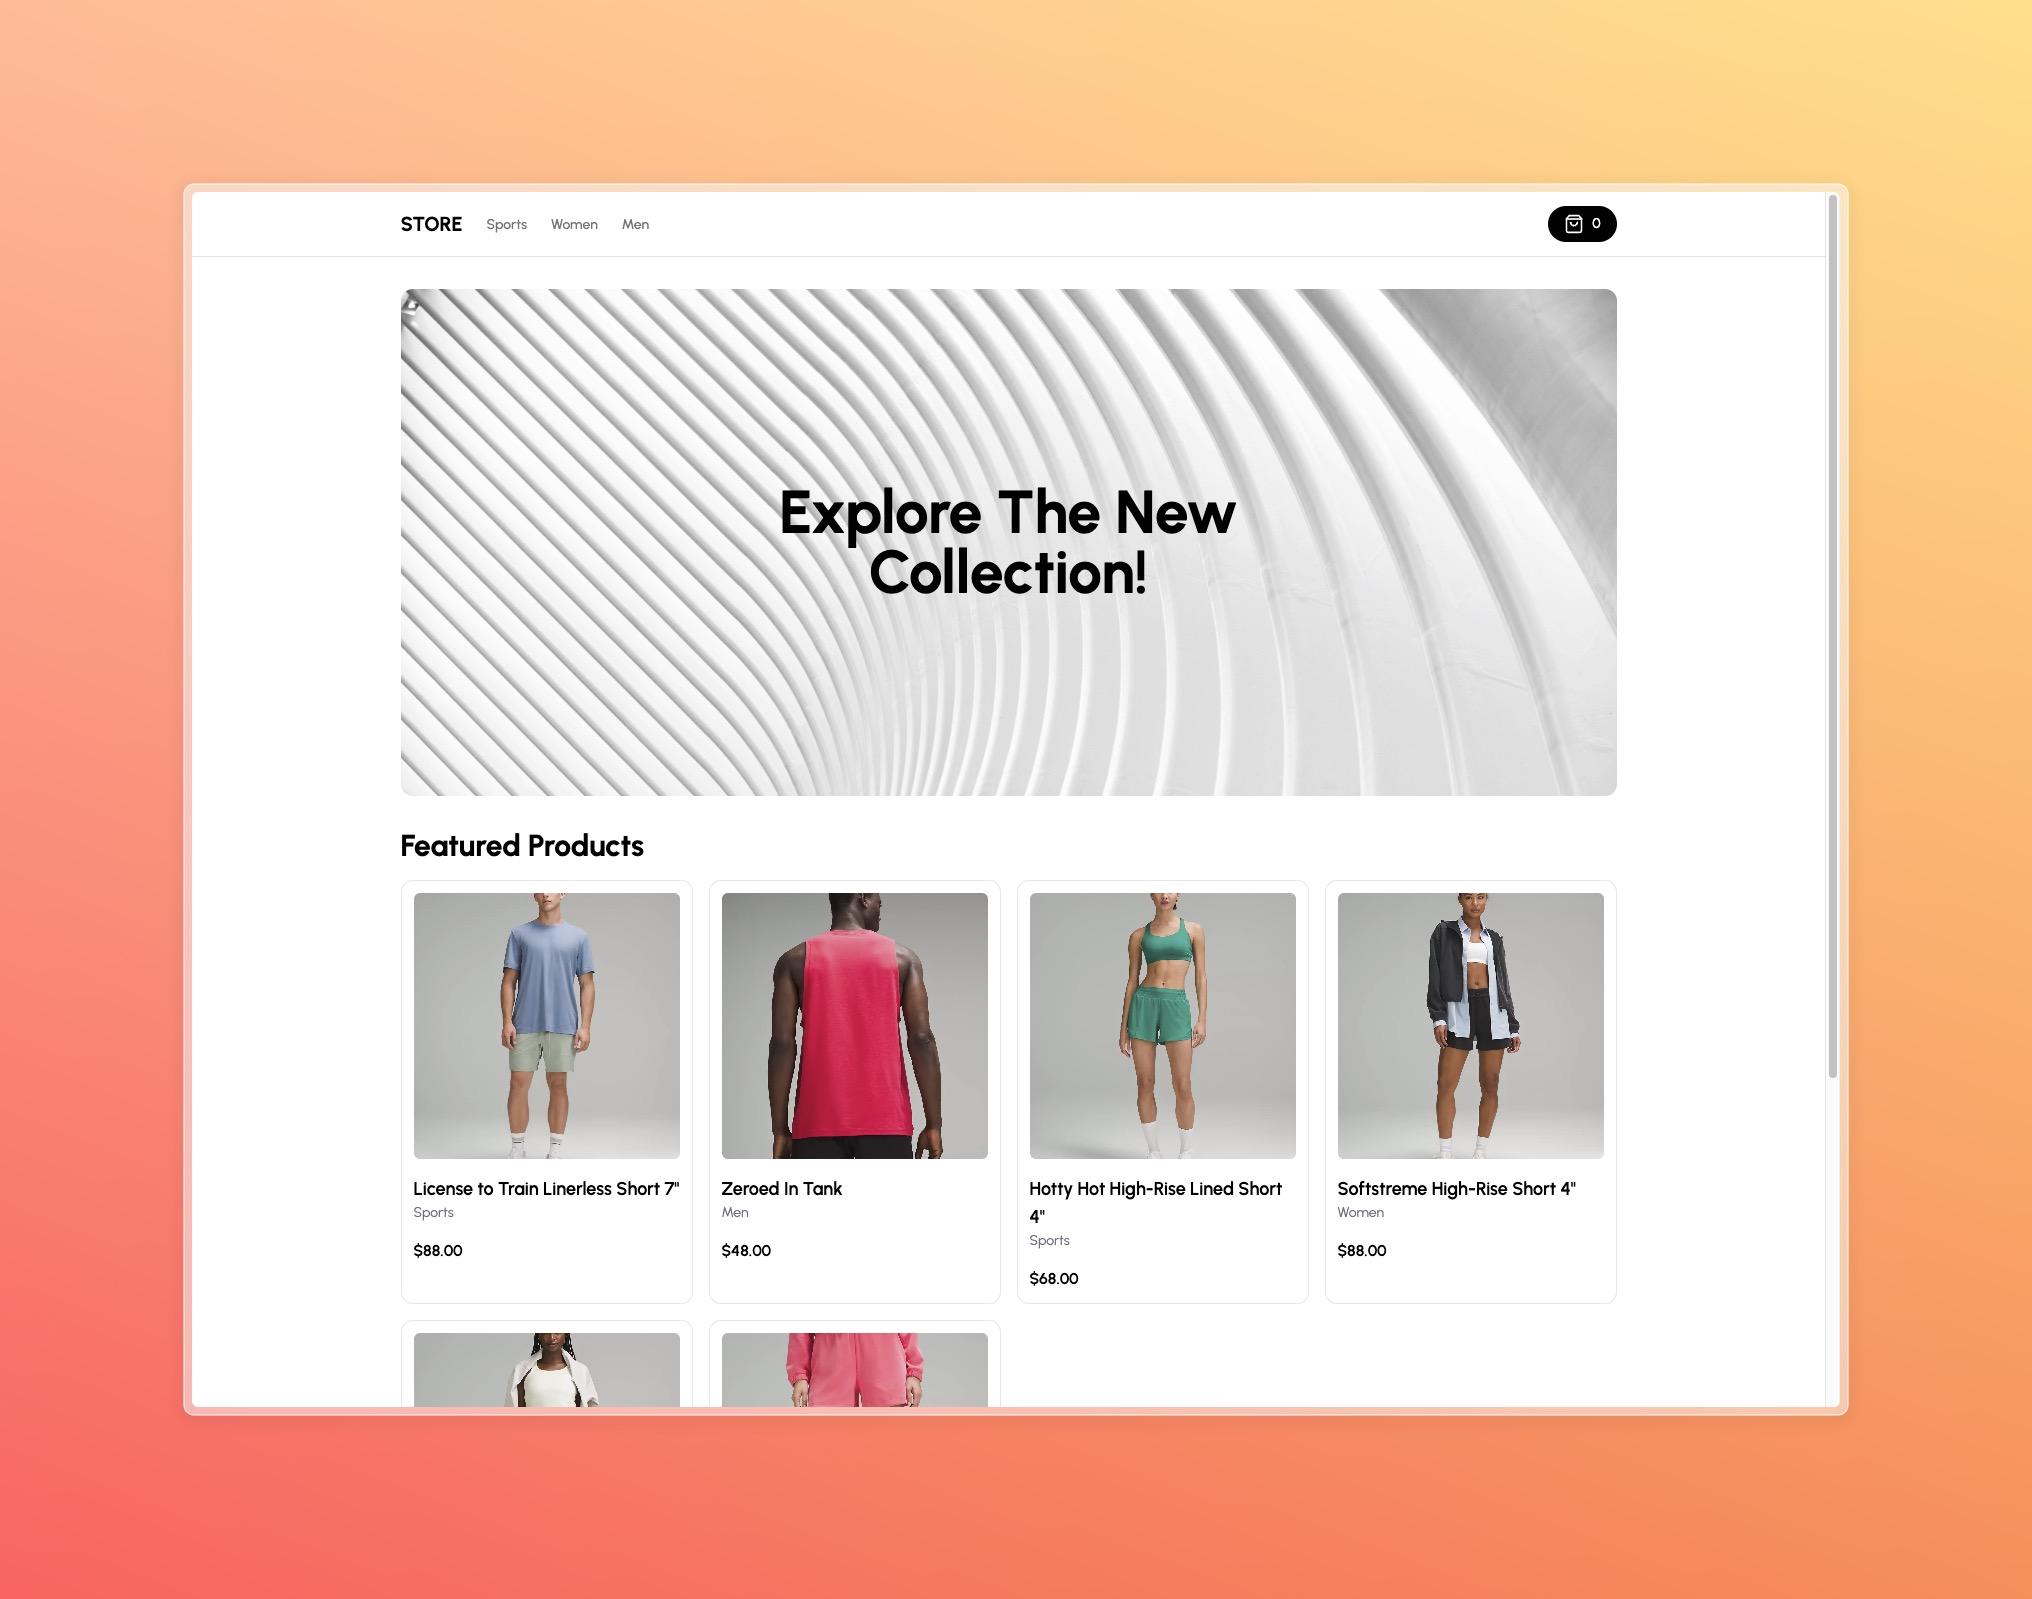
Storefront

Storefront

Modern e-commerce storefront with product catalog, shopping cart, and checkout flow. Headless CMS architecture consuming admin API.

Next.js
React
Tailwind CSS
Stripe

Recent Writing

View all →

Contact

Let's connect

Toronto · Open to backend roles

Education

M.Tech Computer Science
National Institute of Technology, Rourkela
2014–2016
B.Tech Computer Science & Engineering
Uttar Pradesh Technical University, Lucknow
2009–2013